
Core Web Vitals Explained: LCP, INP, CLS, Field Data and Measuring Your Own
Lighthouse says 98. Search Console says your mobile URLs fail Core Web Vitals. Both are telling the truth, they're just measuring different things. Lighthouse loaded your page once, on a simulated device, with a cold cache and nobody clicking anything. Search Console is reporting what happened to real Chrome users over the last month. When they disagree, the real users win.
This post covers the three metrics Google currently treats as Core Web Vitals, how each one is actually calculated, where the numbers come from, and how to collect your own. All thresholds and definitions are from web.dev and the Chrome docs as of November 2026.
The three Core Web Vitals
Per web.dev's Web Vitals overview, the current set is:
- Largest Contentful Paint (LCP), for loading: good is 2.5 seconds or less.
- Interaction to Next Paint (INP), for responsiveness: good is 200 milliseconds or less.
- Cumulative Layout Shift (CLS), for visual stability: good is 0.1 or less.
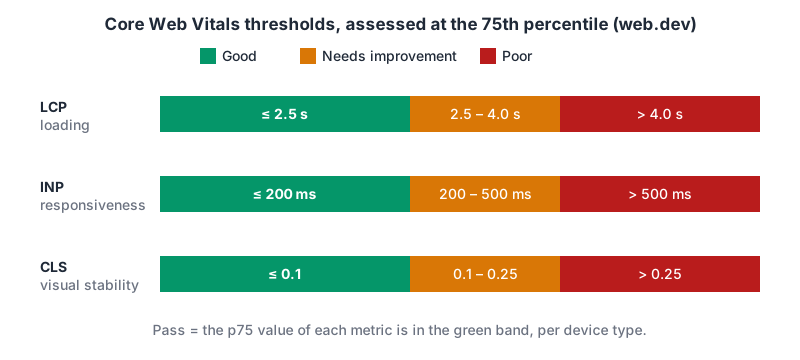
The part people skip: these are assessed at the 75th percentile of page loads, segmented by mobile and desktop. Your median user having a fast page doesn't pass you. A quarter of your visitors can have a bad time and you still pass; more than that and you don't.
The set does change, but slowly. web.dev describes a lifecycle of experimental, pending and stable metrics, and says stable Core Web Vitals won't change more than once a year. The last change was a big one: INP replaced First Input Delay on 12 March 2024. If you have dashboards, alerts or blog posts still talking about FID, they're out of date. Chrome deprecated FID, and the INP launch post gave developers until 9 September 2024 to move off FID in the CrUX and PageSpeed Insights APIs.
LCP: when the main content shows up
LCP is the render time of the largest image, text block or video visible in the viewport, measured from when the user started navigating. Candidates are <img>, <image> inside SVG, <video>, elements with a url() background image, and block-level elements containing text. Chromium ignores elements with zero opacity, elements that cover the whole viewport (treated as background), and low-entropy placeholder images. Reporting stops at the first tap, scroll or keypress.
The most useful thing on web.dev about LCP is the breakdown in Optimize LCP. Every LCP time splits into four parts, with a rough target for each:
| Part | What it is | Target share |
|---|---|---|
| Time to first byte | Server response for the HTML | about 40% |
| Resource load delay | Gap between TTFB and the LCP resource starting to download | under 10% |
| Resource load duration | Downloading the image or font | about 40% |
| Element render delay | Gap between the resource arriving and it painting | under 10% |
The fixes follow from whichever part is big. Long TTFB is a server or caching problem; our posts on HTTP caching headers and Next.js App Router caching cover that side. Long load delay usually means the browser found the image late. The guide's rules: put fetchpriority="high" on the likely LCP image (but on only one or two images, or it stops meaning anything), preload LCP resources that are only referenced from CSS or JavaScript, and "never lazy-load your LCP image." If you're on Next.js, the next/image post covers sizing and loading images properly in Next.js 16.
INP: every interaction, not just the first
INP observes clicks, taps and key presses for the whole visit. Hovering, zooming and scrolling don't count. Each interaction's latency runs from the input to the next frame being painted, in three phases:
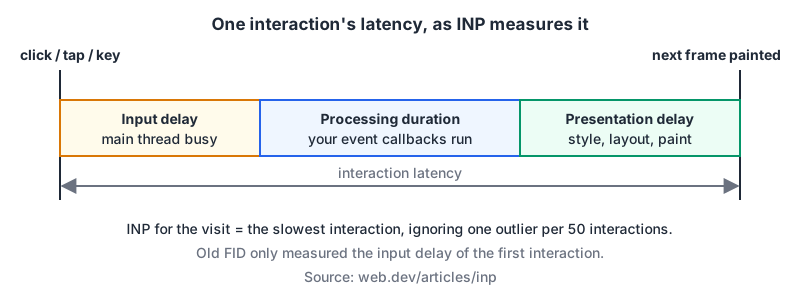
The page's INP is roughly its worst interaction. web.dev says it ignores one highest interaction for every 50, so a page with a few interactions reports its slowest one. Good is 200 ms or less, poor is above 500 ms.
That's why INP is harder than FID was. FID only measured the input delay of the first interaction, which a page could pass just by not doing much on load. INP catches the slow filter dropdown on interaction thirty.
What Optimize INP recommends, in short:
- Reduce input delay: less main-thread work during load (script parsing, compiling and executing), so a click isn't queued behind it.
- Break up long callbacks: update the UI first, then defer the rest to a later task. The article's pattern:
textBox.addEventListener('input', (inputEvent) => {
  updateTextBox(inputEvent); // visible change first

  requestAnimationFrame(() => {
    setTimeout(() => {
      const text = textBox.textContent;
      updateWordCount(text);
      checkSpelling(text);
      saveChanges(text);
    }, 0);
  });
});- Keep rendering cheap: large DOMs make rendering work scale up;
content-visibilitycan defer off-screen rendering.
In React apps, a lot of this is about splitting work and not re-rendering the world on each keystroke. The React performance post and the code-splitting post cover the practical side.
CLS: things moving under the cursor
CLS isn't a running total any more. Shifts are grouped into session windows: shifts less than one second apart, with a window lasting at most five seconds. Your CLS is the score of the worst window. Each shift scores impact fraction × distance fraction, meaning how much of the viewport moved and how far. Good is 0.1 or less, poor is above 0.25.
Shifts within 500 ms of a click, tap or keypress are treated as expected and excluded, so an accordion opening when you click it is fine. The common causes web.dev lists:
- images and videos without dimensions, so space isn't reserved;
- web fonts that render at a different size from the fallback;
- third-party ads or widgets that resize themselves.
Fixes: always set width and height (or aspect-ratio) on media, reserve space for ad slots and embeds, and check that your fallback font takes up roughly the same space as the web font that replaces it. CLS is measured for the whole life of the page in the field, so a banner injected after ten seconds of reading counts, even though Lighthouse will never see it.
Field data vs lab data
web.dev's article on the differences is worth reading in full. Lab tools test one device on one network, usually with a cold cache, and without real user behaviour. That means a lab tool can't measure INP at all ("INP requires real-user interaction"), and only catches load-time layout shifts for CLS. The article's recommendation: when you have both, field data is what you should use to prioritise, and lab data is for debugging and catching regressions.
Lighthouse makes the point on its own: its performance score is a weighted mix of FCP, Speed Index, LCP, Total Blocking Time and CLS. Per the scoring docs, Lighthouse 10 weights them 10%, 10%, 25%, 30% and 25%. TBT stands in for responsiveness because there's no interaction to measure. It's a useful number for comparing two builds; it isn't a Core Web Vital.
Where field data comes from
The Chrome UX Report (CrUX) is Google's public field dataset. It powers PageSpeed Insights' field section and Search Console's Core Web Vitals report. Per the CrUX methodology, it only includes Chrome users who meet its eligibility criteria, only pages that are publicly discoverable and popular enough, and it excludes some platforms, including Chrome on iOS. So a low-traffic page or a logged-in dashboard may have no CrUX data at all.
You can query it directly. The CrUX API needs a Google Cloud API key, returns a 28-day rolling average updated daily, and gives you p75 values:
curl -s "https://chromeuxreport.googleapis.com/v1/records:queryRecord?key=$CRUX_API_KEY" \
  -H 'Content-Type: application/json' \
  -d '{"origin": "https://example.com", "formFactor": "PHONE"}'
The 28-day window is why a fix you shipped yesterday won't show up in Search Console for weeks.
Collecting your own: the web-vitals library
CrUX only covers part of your traffic and lags by weeks. For your own real-user monitoring, Google's web-vitals library is the usual choice. It reports one callback per metric, and each metric object carries a name, value, rating (good, needs-improvement or poor), delta, id and navigationType.
import { onCLS, onINP, onLCP } from 'web-vitals/attribution';

function send(metric) {
  const body = JSON.stringify({
    name: metric.name,
    value: metric.value,
    rating: metric.rating,
    id: metric.id,
    page: location.pathname,
    // the attribution build tells you *why*
    target: metric.attribution?.target ?? metric.attribution?.interactionTarget,
  });
  navigator.sendBeacon('/analytics', body);
}

onCLS(send);
onINP(send);
onLCP(send);
Use the attribution build in production; per the README it adds about 1.5K brotli'd. For LCP it reports the element and the four sub-parts from the table above (timeToFirstByte, resourceLoadDelay, resourceLoadDuration, elementRenderDelay). For INP it gives the interaction target, type, the three phases and the longest script involved. That's the difference between "INP is bad" and "the filter button on /search spends 300 ms in processing."
A few details from the README: some metrics only report after interaction, a tab switch or unload, so send with sendBeacon rather than waiting for a fetch; reportAllChanges exists but isn't recommended in production; and browser support differs per metric. As of November 2026 the README lists onCLS() as Chromium-only, while INP, LCP, FCP and TTFB work in Chromium, Firefox and Safari. Aggregate at the 75th percentile per page template and device type, the same way CrUX does, or your numbers won't line up with Search Console.
What to actually do
- Check field data first: PageSpeed Insights or the CrUX API for your top templates, phone form factor.
- Pick the metric that fails at p75 and ignore the Lighthouse score for now.
- Add
web-vitals/attributionreporting so you know which element or interaction is responsible. - Use lab tools (Lighthouse, DevTools performance panel) to reproduce and fix that specific problem.
- Set a budget so it doesn't regress; the performance budgets guide is the next read.
- Wait for the 28-day window before declaring victory in Search Console.
Written by AIDToolStack Editorial
Researched from official documentation, specifications and vendor pages, listed under Sources below. Last checked November 2026.
Sources
- web.dev/articles/vitals
- web.dev/blog/inp-cwv-march-12
- web.dev/blog/inp-cwv-launch
- web.dev/articles/lcp
- web.dev/articles/optimize-lcp
- web.dev/articles/inp
- web.dev/articles/optimize-inp
- web.dev/articles/cls
- web.dev/articles/lab-and-field-data-differences
- developer.chrome.com/docs/lighthouse/performance/performance-scoring
- developer.chrome.com/docs/crux/methodology
- developer.chrome.com/docs/crux/api
- github.com/GoogleChrome/web-vitals
Related Posts
Explore on AIDToolStack
Discover tools and servers featured in our directory.
AI Tools
MCP Servers
Sponsor Our Newsletter
Reach thousands of developers who are actively evaluating AI tools, MCP servers, and dev infrastructure. Our weekly newsletter goes to engaged technical decision-makers.
All sponsored content is clearly labeled per our editorial policy.