
How LLMs Read Your Code: Tokens, Context Windows, Attention and Repo Maps
You ask an assistant to add a method to your API client. It writes clean code that calls client.users.findByEmail(). That method doesn't exist and never has. The code looks right, it matches the style of the file, and it fails the moment you run it.
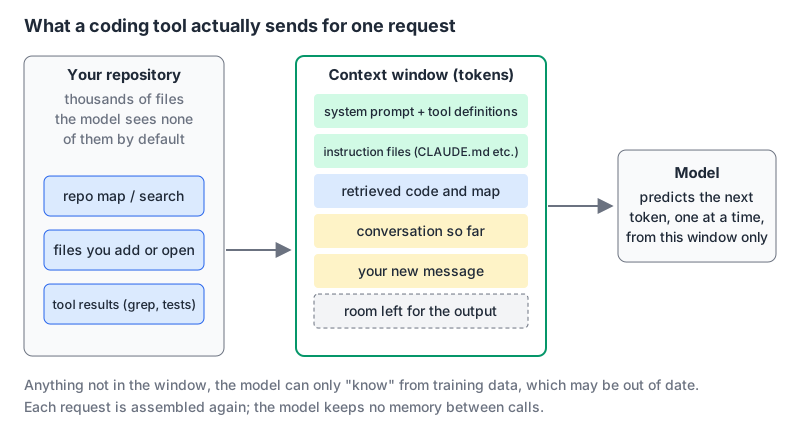
That failure isn't random. It falls straight out of how these models take in code: as tokens, inside a fixed-size window, with no memory of your repo beyond what the tool put in that window for this one request. Once you see the pipeline, most of the odd behavior stops being odd, and you can work with it instead of being surprised by it.
Tokens: your code isn't read as code
Before a model sees anything, a tokenizer chops the text into integer IDs. OpenAI's tiktoken is the tokenizer for its models, and its README gives the rule of thumb: "each token corresponds to about 4 bytes" on average. Google's token docs say much the same for Gemini, about 4 characters per token.
Averages hide the interesting part. I ran a few lines of ordinary code through tiktoken 0.14.0 with the o200k_base encoding, which is what tiktoken.encoding_for_model("gpt-4o") returns:
import tiktoken

enc = tiktoken.get_encoding("o200k_base")
for s in ["const user = await getUserById(id);",
          "const usr = await fetchUsrByIdV2(uid);",
          "0x7fffffff"]:
    ids = enc.encode(s)
    print(len(ids), [enc.decode([i]) for i in ids])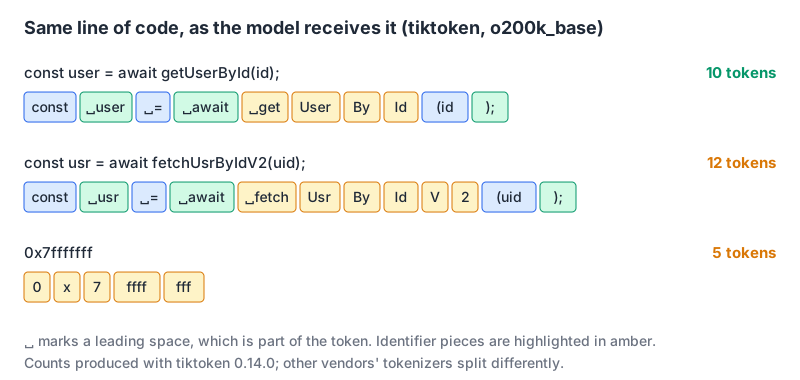
The results, all real output from that script:
| Input | Tokens | How it splits |
|---|---|---|
getUserById | 4 | get User By Id |
XMLHttpRequest | 3 | XML Http Request |
def get_user_by_id(user_id: int) -> User: | 13 | def get _user _by _id (user _id ... |
kubectl rollout restart deployment/api | 6 | kub ectl rollout restart ... |
0x7fffffff | 5 | 0 x 7 ffff fff |
1234567890 | 4 | 123 456 789 0 |
four spaces + return x + newline | 4 | return x newline |
tab + return x + newline | 3 | \treturn x newline |
A few things fall out of this.
Identifiers are word pieces. getUserById isn't one symbol to the model; it's four common fragments that appear in millions of other identifiers. That's why a model happily produces getUserByEmail or findUserById: each is a very likely sequence of the same pieces. The model is predicting plausible fragments, not looking up your symbol table.
Odd names cost more and carry less. fetchUsrByIdV2 takes more tokens than the conventional name, and Usr, V, 2 give the model less to go on. Descriptive, conventional names aren't just for humans.
Numbers are chunked arbitrarily. 1234567890 becomes 123|456|789|0. A model doing arithmetic on literals, or comparing version strings, is working on those chunks. Don't trust it to compute a bitmask; ask it to write code that computes it.
Tokenizers differ by vendor and by model. These counts are for one OpenAI encoding. Anthropic's token counting docs say Claude Opus 4.7 and later use a newer tokenizer that produces "approximately 30 percent more tokens" for the same text than earlier Claude models. Count with the vendor's own tool (Anthropic's count_tokens endpoint is free, rate-limited per tier) rather than reusing someone else's numbers. Our token counter estimates from character and word counts, which is fine for a rough budget; for billing-grade numbers use the provider's API.
The context window is the model's entire world
The Claude context window docs define it as "all the text a language model can reference when generating a response, including the response itself." Everything counts: system prompt, tool definitions, every message, tool results, and the output. As of November 2026, current Claude models (Opus 4.6 onward, Sonnet 4.6 onward, Haiku 5.5) have a 1M-token window with up to 128k output tokens per request, while older ones such as Sonnet 4.5 stay at 200k. OpenAI's models page lists 1.05M tokens of context and 128K max output for its current flagship GPT-6 models.
A million tokens sounds like "the whole repo fits." Two catches.
First, size isn't quality. The same Anthropic page says "more context isn't automatically better" and names the effect: as token count grows, "accuracy and recall degrade," which it calls context rot. The older research result points the same way. Lost in the Middle (Liu et al., TACL 2023) found performance "is often highest when relevant information occurs at the beginning or end of the input context," and dropped when the useful part sat in the middle.
Second, the window is rebuilt on every request. The model has no memory between API calls; the tool resends the conversation each turn. If the conversation got compacted or trimmed, the convention you explained forty turns ago may simply not be there anymore. When you overflow, the API tells you: Claude returns a 400 invalid_request_error ("prompt is too long") if the input alone is too big.
Attention, without the math
Inside the window, the transformer's job is to decide which earlier tokens matter for predicting the next one. That's attention, from the 2017 paper Attention Is All You Need (Vaswani et al.), which built the architecture on attention mechanisms alone and dropped the recurrent and convolutional layers that came before.
Conceptually: for each position, the model scores every earlier token for relevance and mixes in information from the high scorers. When you write user. inside a function, the tokens of the User type definition (if it's in the window) can get high weight, which is how the model "knows" the fields. If the definition isn't in the window, attention has nothing to find, and the model falls back on what User objects usually look like in its training data.
That's the core mental model. The model doesn't parse your code, build an AST, or resolve imports. It learns statistical relationships between tokens that happen to capture a lot of syntax and semantics, and it applies them to whatever is in front of it.
Why models invent APIs
Put the three pieces together and hallucinated APIs are the expected failure, not a weird one:
- The real method signature isn't in the window.
- The tokens for a plausible method (
findByEmail) are each highly probable. - Nothing in the generation step checks that the symbol exists.
Training data adds a time dimension. The model learned a library as it was at its training cutoff, so renamed functions and changed defaults come out in their old form with total confidence.
It's measurable at scale. We Have a Package for You! (Spracklen et al.) generated 576,000 code samples across 16 models in Python and JavaScript and found that at least 5.2% of recommended packages were hallucinated for commercial models and 21.7% for open-source ones, with 205,474 unique made-up package names. That's a supply-chain problem as well as a correctness one: someone can register the name a model keeps inventing.
What helps, in order of payoff:
- Let a compiler, type checker or test run see the code before you do. A nonexistent method dies at
tsc --noEmitin seconds. - Put the real interface in the window: open the file, paste the type, or let the tool search for it.
- For third-party libraries, feed current docs. The Context7 MCP server exists for this: it pulls version-specific docs and examples into the prompt.
- Check that every new dependency exists, is the package you meant, and is maintained, before
npm install.
How tools decide what goes into the window
Since the window is everything, the interesting engineering in coding assistants is context selection. Three approaches show up repeatedly.
Repository maps. Aider's repo map is the clearest documented example. It sends the model "a list of the files in the repo, along with the key symbols which are defined in each file," shown as signatures with the bodies elided. Aider's write-up on the design explains that it uses tree-sitter to parse each file into an AST, finds where functions, classes and types are defined and where they're referenced, then runs a graph ranking over files to keep the most-referenced identifiers. The budget is set by --map-tokens, which "defaults to 1k tokens," and Aider grows it when no files are in the chat. A map is cheap and gives the model the shape of the codebase so it reuses UserRepository.findByEmail instead of inventing one.
Agentic search. Tools like Claude Code give the model grep, file reads and shell commands, and let it pull in what it needs. Results land in the window as tool output and count toward the limit like everything else. The Aider vs Claude Code comparison covers how the two approaches feel in practice.
Embedding retrieval. Index code or docs as vectors, fetch the nearest chunks per question. It works better for prose docs than for code, where exact symbol names matter; our post on RAG for developer documentation goes through it.
A working checklist
- Keep the window focused: start a fresh session for an unrelated task rather than dragging the old history along.
- Put the definitions the model needs in the window explicitly. Don't count on it remembering something from a long way back.
- Treat any API you didn't see in the window as a guess until a compiler or test confirms it.
- Ask for code that computes values, not for the values themselves.
- Use conventional names; they tokenize into fragments the model has seen countless times.
- Measure tokens with the provider's counter for the exact model you'll run, especially after a model upgrade.
- If you're building on the APIs directly, our LLM API best practices guide covers budgeting and retries.
Written by AIDToolStack Editorial
Researched from official documentation, specifications and vendor pages, listed under Sources below. Last checked November 2026.
Sources
- github.com/openai/tiktoken
- aistudio.google.com/docs/tokens
- platform.claude.com/docs/en/build-with-claude/token-counting
- platform.claude.com/docs/en/build-with-claude/context-windows
- developers.openai.com/api/docs/models
- arxiv.org/abs/2307.03172
- arxiv.org/abs/1706.03762
- arxiv.org/abs/2406.10279
- github.com/upstash/context7
- aider.chat/docs/repomap.html
- aider.chat/2023/10/22/repomap.html
Explore on AIDToolStack
Discover tools and servers featured in our directory.
AI Tools
MCP Servers
Sponsor Our Newsletter
Reach thousands of developers who are actively evaluating AI tools, MCP servers, and dev infrastructure. Our weekly newsletter goes to engaged technical decision-makers.
All sponsored content is clearly labeled per our editorial policy.